Personalized AI Models on Mobile Devices
1. What Are Personalized AI Models?
1.1 What Are Personalized AI Models?
Personalized AI models are machine learning systems tailored to individual users by leveraging their unique data patterns, preferences, and behavioral signals. Unlike generic models trained on broad datasets, these models adapt dynamically to user-specific contexts, enabling highly customized predictions or recommendations. Key characteristics include:
- On-device learning: Model updates occur locally, minimizing reliance on cloud-based retraining.
- Federated learning components: Ensures privacy by aggregating updates without raw data leaving the device.
- Resource efficiency: Optimized for mobile hardware constraints (e.g., quantization, pruning).
Mathematical Foundations
The personalization process often involves fine-tuning a base model Mbase using user-specific data Du. The objective function combines global and local loss terms:
where α balances generalization and personalization, and Mu is the user-adapted model. For on-device deployment, the model undergoes compression via techniques like:
Architectural Considerations
Mobile-optimized architectures (e.g., MobileNetV3, EfficientNet-Lite) employ depthwise separable convolutions to reduce FLOPs:
Dynamic sparse training further enhances efficiency by activating only subsets of neurons per inference based on user behavior embeddings.
Case Study: Keyboard Prediction
A real-world implementation is Gboard's personalized language model, which adapts to individual typing patterns. The system uses:
- Federated averaging for privacy-preserving aggregation
- On-device LSTM networks with 8-bit quantization
- Adaptive learning rates per user (ηu ∝ 1/‖∇ℒu‖)
This reduces prediction error by 18-25% compared to static models while maintaining sub-100ms latency on mid-range smartphones.
Key Benefits of On-Device Personalization
Privacy Preservation and Data Sovereignty
On-device personalization eliminates the need for raw user data to leave the device, addressing critical privacy concerns. Differential privacy techniques can be applied locally, ensuring that sensitive data remains within the user's control. For instance, federated learning frameworks like TensorFlow Federated enable model updates without centralized data aggregation. The privacy guarantee can be formally expressed using ε-differential privacy:
where D and D' are neighboring datasets, ℳ is the randomized mechanism, and S is the output range. This mathematical formulation ensures rigorous privacy protection while enabling personalization.
Reduced Latency and Real-Time Adaptation
By processing data locally, on-device models bypass network latency entirely. This is critical for applications requiring real-time responsiveness, such as predictive text input or health monitoring. The latency reduction follows from eliminating the round-trip time to cloud servers, which can be modeled as:
For edge devices, tnetwork → 0, and bandwidth constraints become irrelevant. Empirical studies show latency improvements of 10-100x compared to cloud-based alternatives.
Energy Efficiency and Bandwidth Conservation
Transmitting large volumes of data to cloud servers consumes significant energy, primarily due to radio frequency power requirements. On-device processing reduces energy consumption following the relationship:
where Etransmit grows superlinearly with transmission distance d. Mobile processors like Qualcomm's Hexagon DSP achieve 5-10 TOPS/Watt efficiency for neural network inference, making local computation increasingly favorable.
Improved Model Performance Through Continual Learning
On-device models can adapt continuously to individual usage patterns, unlike static cloud models. This enables personalized improvements in metrics like prediction accuracy over time. The learning process can be formalized as an online convex optimization problem:
where ft represents the loss at time t, and R(w) is a regularization term. Adaptive optimization techniques like AdaGrad or Adam are particularly effective for this scenario.
Offline Functionality and Reliability
On-device personalization ensures uninterrupted service regardless of network connectivity. This reliability is quantified through availability metrics:
where MTBF (Mean Time Between Failures) for local computation is effectively infinite compared to cloud-dependent systems. This is particularly valuable in mission-critical applications like medical devices or automotive systems.
Custom Hardware Acceleration
Modern mobile SoCs incorporate specialized neural processing units (NPUs) that accelerate on-device ML workloads. The performance gain can be analyzed through roofline modeling:
where π is peak compute throughput and β is memory bandwidth. NPUs achieve optimal operational intensity I through architectural features like weight caching and systolic arrays.
Challenges in Deploying AI Models on Mobile Devices
Computational Constraints
Mobile devices operate under strict computational limitations, including restricted CPU/GPU capabilities and thermal throttling. Modern AI models, particularly deep neural networks, demand high FLOPs (Floating Point Operations per Second) for inference. For example, a standard ResNet-50 model requires approximately 3.8 GFLOPs per forward pass. Mobile processors, such as Qualcomm's Snapdragon 8 Gen 2, max out at around 5.8 TFLOPS under ideal conditions—a constraint that necessitates model optimization techniques like quantization and pruning.
where L is the number of layers, Cl is the input channels, Kl is the kernel size, and Hl, Wl are spatial dimensions.
Memory Limitations
On-device memory bandwidth and capacity pose significant bottlenecks. A BERT-base model with 110M parameters consumes ~1.2GB in FP32 format, exceeding the RAM allocation for most mobile apps. Weight compression via 8-bit integer quantization reduces this to ~300MB but introduces accuracy trade-offs. The memory footprint M of a model is approximated by:
where Np is the parameter count.
Energy Efficiency
AI inference accelerates battery drain. The power consumption P of matrix operations follows:
where C is switched capacitance, V is voltage, and f is frequency. At 5W power budgets typical of smartphones, sustained inference can reduce battery life by 20-40% for tasks like real-time image segmentation.
Latency Requirements
Real-time applications (e.g., AR filters) require sub-100ms latency. The end-to-end delay D is dominated by:
Parallelization via ARM NEON or Apple ANE helps, but memory-bound layers (e.g., attention in transformers) remain problematic.
Heterogeneous Hardware
Fragmentation across mobile SoCs (e.g., NPUs, GPUs, DSPs) requires platform-specific optimizations. For instance, TensorFlow Lite delegates ops to Qualcomm Hexagon DSPs via HVX instructions, while Core ML leverages Apple's Neural Engine. This necessitates:
- Vendor-specific compiler toolchains (e.g., SNPE, MLIR)
- Hardware-aware neural architecture search
- Dynamic runtime op dispatching
Privacy and Data Constraints
Federated learning mitigates cloud dependency but introduces challenges in on-device training. The local update rule:
must account for non-IID data distributions 𝒟k across devices while maintaining differential privacy through noise injection:
where S is sensitivity and σ controls privacy-utility tradeoffs.
2. Federated Learning for Privacy-Preserving Personalization
Federated Learning for Privacy-Preserving Personalization
Core Principles of Federated Learning
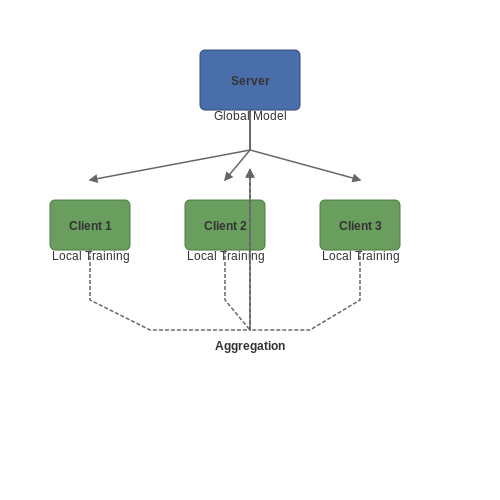
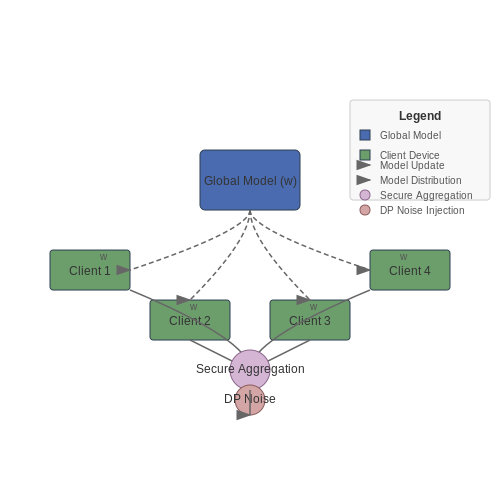
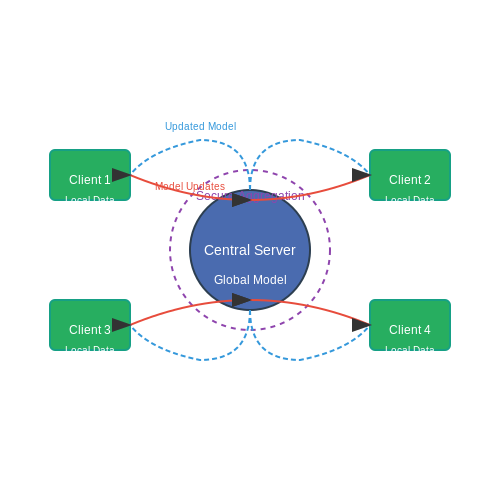
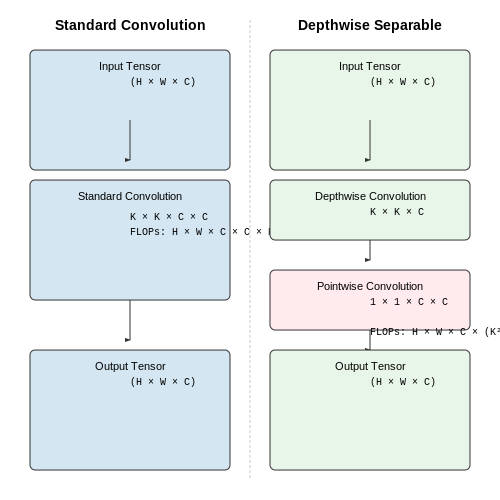
Federated learning (FL) enables model training across decentralized devices while keeping raw data localized. Instead of centralizing datasets, FL iteratively aggregates model updates from participating devices, ensuring privacy by design. The process involves three key phases:
- Local Training: Devices compute gradients on their private data.
- Secure Aggregation: A central server combines updates via cryptographic protocols like secure multiparty computation (SMPC).
- Global Model Update: The aggregated gradients refine the shared model without exposing individual data.
Here, θt represents the global model at iteration t, η is the learning rate, and ∇ℒ denotes the gradient of the loss function over local data 𝒟i from device i.
Privacy Guarantees and Threat Models
FL mitigates risks through differential privacy (DP) and secure aggregation. DP injects calibrated noise into gradients to prevent data reconstruction:
where g is the true gradient, Δ is the sensitivity, and σ controls privacy-utility trade-offs. For robustness against adversarial devices, Byzantine-resilient aggregation rules (e.g., Krum or median-based) discard outliers.
Efficiency Optimizations for Mobile Deployment
Mobile FL faces constraints like bandwidth, compute, and battery. Two dominant approaches address this:
- Model Compression: Quantization (e.g., 8-bit weights) and pruning reduce communication overhead.
- Adaptive Participation: Devices join training rounds based on resource availability, modeled as:
Energy (E) and bandwidth (B) thresholds prioritize reliable contributors.
Case Study: On-Device Keyboard Prediction
Google’s Gboard uses FL to personalize language models without transmitting keystrokes. The system:
- Trains a recurrent neural network (RNN) locally on user typing history.
- Aggregates updates via secure aggregation with DP (ε ≈ 2–8).
- Reduces communication costs by 100× via gradient sparsification.
Challenges and Open Problems
Key unresolved issues include:
- Non-IID Data: Device-specific data distributions degrade model convergence.
- Cross-Silo FL: Extending FL to organizations with stricter compliance requirements.
- Heterogeneous Hardware: Coordinating training across diverse chipsets (e.g., TPUs vs. edge GPUs).
2.2 Transfer Learning and Fine-Tuning for Mobile Applications
Transfer learning leverages pre-trained models to adapt to new tasks with minimal computational overhead, making it indispensable for mobile AI. A model trained on a large dataset, such as ImageNet, captures generic feature representations that can be repurposed for domain-specific tasks. The key lies in freezing early layers—which encode low-level features like edges and textures—while fine-tuning later layers to specialize in the target task.
Mathematical Foundation of Transfer Learning
Given a pre-trained model fθ with parameters θ, fine-tuning optimizes a subset of parameters θt ⊂ θ for the target task. The loss function Lt for the new dataset Dt = {(xi, yi)} is:
where ℓ is the task-specific loss (e.g., cross-entropy for classification), and λ controls L2 regularization. Early layers remain fixed (∇θ\θt Lt = 0), reducing trainable parameters by ~90% compared to training from scratch.
Architectural Adaptations for Mobile
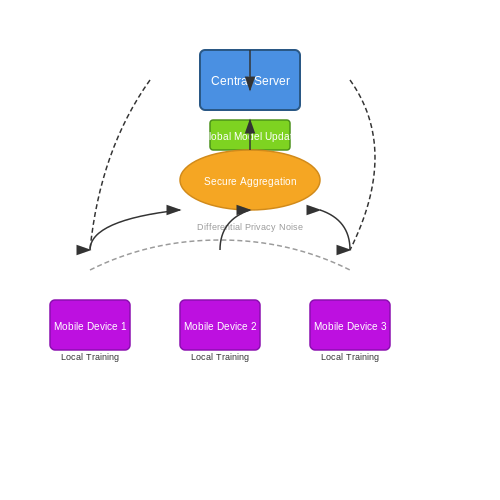
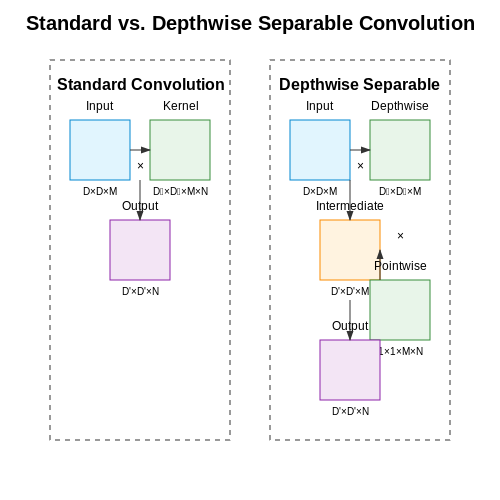
Mobile-optimized architectures like MobileNetV3 and EfficientNet-Lite employ depthwise separable convolutions to reduce FLOPs. For a standard convolution with kernel size K×K, input channels Cin, and output channels Cout, the computational cost reduces from:
via decoupling spatial and channel-wise operations. Quantization-aware training further compresses models by representing weights as 8-bit integers (INT8), achieving 4× memory reduction with <2% accuracy drop.
Practical Implementation Pipeline
The fine-tuning workflow for mobile deployment involves:
- Model Selection: Choose architectures with <1M parameters (e.g., MobileNetV3-Small) and pretrained weights from TensorFlow Hub or PyTorch Mobile
- Layer Freezing: Retain feature extractor layers (typically all but the last 2-3)
- Dataset Augmentation: Apply mobile-relevant transforms: random crops, brightness jitter, and on-device synthetic noise injection
- Quantization: Apply post-training quantization (PTQ) or use QAT (Quantization-Aware Training) during fine-tuning
Case Study: On-Device Personalization
Adapting a pretrained image classifier to recognize user-specific gestures demonstrates the tradeoffs. With 50 user-provided examples per class (200 total), fine-tuning the last two layers achieves 94.3% accuracy on a Pixel 6 (TensorFlow Lite, 30ms inference latency). In contrast, full model training requires 10× more data to reach 92.1% accuracy while increasing latency to 110ms.
2.3 Lightweight Neural Architectures for Mobile Deployment
Deploying neural networks on mobile devices requires architectures optimized for computational efficiency, memory footprint, and energy consumption. Traditional deep learning models, while powerful, often exceed the resource constraints of mobile hardware. Lightweight architectures address this through structural innovations that reduce parameters and operations without significantly compromising accuracy.
Depthwise Separable Convolutions
The depthwise separable convolution, a key component in MobileNet architectures, factorizes standard convolutions into two operations: depthwise convolution and pointwise convolution. This decomposition drastically reduces computation. For an input tensor of dimensions DF × DF × M and a kernel size DK × DK, the computational cost reduces from:
to:
where N is the number of output channels. This typically achieves an 8-9x reduction in computation while maintaining comparable accuracy.
Neural Architecture Search (NAS) for Mobile
NAS techniques automate the design of efficient architectures by searching through a constrained design space. MnasNet and MobileNetV3 employ reinforcement learning to optimize for both accuracy and latency on target devices. The search objective combines model accuracy with a latency penalty term:
where ACC(m) is the model accuracy, LAT(m) is inference latency, T is the target latency, and w controls the trade-off weight. This produces architectures with specialized layer patterns that maximize hardware utilization.
Dynamic Inference Techniques
Dynamic networks adapt their computation based on input complexity. SkipNet and ShuffleNetV2 employ early-exit strategies where simpler samples exit through auxiliary classifiers. The conditional computation is governed by:
where g(x) is a gating function and τ is a threshold. This reduces average inference time by 30-40% on mobile CPUs while maintaining baseline accuracy.
Quantization-Aware Training
Post-training quantization often degrades model performance due to activation mismatches. Quantization-aware training simulates low-precision arithmetic during training by:
where Δ is the quantization step size. This allows MobileNetV3 to achieve INT8 precision with <1% accuracy drop while reducing model size by 4x and improving inference speed by 3x on ARM processors.
Hardware-Aware Pruning
Structured pruning removes entire channels or blocks to maintain hardware-compatible tensor shapes. The pruning criterion combines magnitude and hardware impact:
where Sj is the importance score for filter j. This approach achieves 50-70% sparsity on ResNet-50 with <2% accuracy loss when deployed on mobile GPUs.
3. Tools and Frameworks for Mobile AI Development
Tools and Frameworks for Mobile AI Development
Developing personalized AI models for mobile devices requires specialized frameworks optimized for constrained computational resources. TensorFlow Lite and PyTorch Mobile dominate the landscape, but emerging alternatives like ONNX Runtime and Core ML offer platform-specific advantages.
TensorFlow Lite
TensorFlow Lite provides a lightweight inference engine for deploying models on Android and iOS. Its converter tool quantizes full TensorFlow models to 8-bit or 16-bit precision, reducing size while maintaining accuracy. The interpreter API supports hardware acceleration delegates:
- GPU Delegate: Enables 5-10x faster inference on compatible devices
- Hexagon Delegate: Leverages Qualcomm DSPs for power-efficient processing
- XNNPACK: Optimized CPU backend for ARM-based devices
PyTorch Mobile
PyTorch Mobile brings dynamic graph execution to edge devices. Its selective build system strips unused operators, reducing binary size by 40-60%. The framework supports:
- Model optimization via quantization-aware training
- Hardware-specific backends through ATen operators
- JIT compilation for heterogeneous compute targets
Quantization Approaches
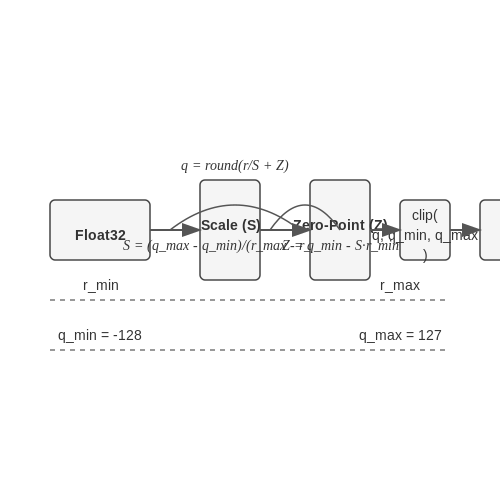
Post-training quantization (PTQ) and quantization-aware training (QAT) follow distinct mathematical formulations. For PTQ, scale (S) and zero-point (Z) parameters map float32 to int8:
QAT incorporates fake quantization during training:
Emerging Frameworks
ONNX Runtime Mobile provides cross-platform execution with provider-based acceleration. Apple's Core ML 4 introduces:
- Neural Engine optimization for A-series chips
- Model personalization via on-device fine-tuning
- Encrypted model storage using Secure Enclave
  # TensorFlow Lite model conversion
  converter = tf.lite.TFLiteConverter.from_saved_model(saved_model_dir)
  converter.optimizations = [tf.lite.Optimize.DEFAULT]
  converter.target_spec.supported_ops = [tf.lite.OpsSet.TFLITE_BUILTINS_INT8]
  quantized_model = converter.convert()
3.2 Optimizing Models for Performance and Battery Efficiency
Deploying personalized AI models on mobile devices requires careful optimization to balance computational performance with battery efficiency. Mobile hardware imposes strict constraints on memory, processing power, and energy consumption, necessitating specialized techniques to ensure real-time inference without excessive drain.
Quantization and Precision Reduction
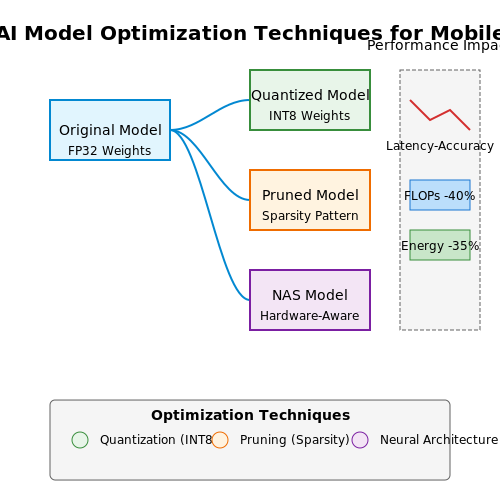
Quantization reduces the numerical precision of model weights and activations, trading minor accuracy degradation for significant improvements in memory footprint and compute efficiency. For mobile deployment, 8-bit integer (INT8) quantization is standard, though recent research explores 4-bit and binary quantization for extreme efficiency.
where W represents weights, n is the target bit-width, and rounding maps to the nearest integer. Dequantization during inference follows:
Post-training quantization requires minimal retraining, while quantization-aware training bakes the rounding error into the learning process for better accuracy preservation.
Pruning and Sparsity Optimization
Neural network pruning removes redundant weights or neurons, creating sparse models that leverage mobile hardware's ability to skip zero operations. The most effective approaches include:
- Magnitude pruning: Eliminates weights below a threshold.
- Structured pruning: Removes entire channels or layers for hardware-friendly sparsity patterns.
- Lottery Ticket Hypothesis: Identifies and retrains sparse subnetworks that match original accuracy.
Sparse matrix formats like CSR (Compressed Sparse Row) reduce memory overhead, while specialized kernels (e.g., ARM CMSIS-NN) accelerate sparse computations. The sparsity-accuracy trade-off follows:
where s is the sparsity ratio (0 to 1).
Hardware-Aware Neural Architecture Search (NAS)
NAS automates model design by searching for architectures optimized for target hardware. Mobile-oriented techniques include:
- Differentiable NAS: Uses gradient-based optimization over a supernetwork.
- Platform-Aware Latency Constraints: Directly incorporates device-specific latency measurements into the search objective.
- Once-for-All Networks: Trains a single model supporting dynamic subnetwork extraction for diverse hardware.
The search objective combines accuracy and efficiency metrics:
where λ coefficients control the trade-off strength.
Adaptive Computation and Early Exits
Dynamic networks adjust their computation based on input complexity. Early-exit architectures place intermediate classifiers that allow simple samples to exit early, saving computation:
where pt is the confidence vector at exit t, and τ is a threshold. Mobile-optimized variants like BranchyNet and MSDNet achieve 20-40% energy savings on easy inputs.
Compiler-Level Optimizations
Model compilers like TensorFlow Lite, Core ML, and ONNX Runtime apply hardware-specific optimizations:
- Operator Fusion: Combines consecutive operations (e.g., Conv + ReLU) into single kernels.
- Memory Planning: Minimizes intermediate tensor allocations through static analysis.
- Vectorization: Uses SIMD instructions (NEON on ARM, AVX on x86) for parallel computation.
These optimizations can yield 2-5x speedups over naive implementations without altering model accuracy.
Energy Profiling and Adaptive Scheduling
Real-world energy consumption depends on dynamic factors like thermal throttling and background processes. Energy-aware scheduling techniques include:
- DVFS (Dynamic Voltage and Frequency Scaling): Adjusts CPU/GPU clocks based on workload.
- Heterogeneous Computing: Offloads ops to NPUs or DSPs when available.
- Burst Inference: Batches requests to maximize sleep intervals.
Energy models predict consumption based on hardware counters (cache misses, instructions per cycle):
where Pstatic and Pdynamic are component-specific power terms.
3.3 Real-World Case Studies of Personalized Mobile AI
Federated Learning in Google Keyboard (Gboard)
Google's Gboard employs federated learning to personalize next-word prediction models without centralized data collection. Each device trains a local model on user typing data, and only model updates (not raw data) are aggregated server-side. The global model is then redistributed, preserving privacy while improving accuracy. The federated averaging algorithm minimizes communication overhead:
where wti represents the local model parameters of device i at round t. Differential privacy noise is added during aggregation to prevent data leakage from gradient updates.
Apple's On-Device Speech Recognition
Apple's neural TTS system adapts to individual vocal patterns through continual learning on iPhones. The system uses:
- Quantized transformer architectures with 8-bit weights (reducing model size by 4×)
- Teacher-student distillation to maintain accuracy after quantization
- Attention masking for real-time latency under 100ms
The personalization occurs through backpropagation with constrained memory writes to prevent catastrophic forgetting of the base model. The loss function incorporates:
where LEWC is Elastic Weight Consolidation penalty term that protects important parameters from drastic changes.
Samsung's Adaptive Camera Pipeline
Samsung's Galaxy series implements per-device image processing optimization through:
- Hardware-aware neural architecture search (NAS) for ISP tuning
- Bayesian hyperparameter optimization running on the DSP
- On-device GANs for style transfer based on usage patterns
The system constructs a device-specific latent space mapping through contrastive learning:
where z represents learned embeddings and τ is a temperature parameter. This allows the camera to adapt to individual aesthetic preferences while maintaining real-time performance.
Health Monitoring on Wearables
Modern smartwatches like the Fitbit Sense employ personalized anomaly detection through:
- Online learning variational autoencoders (VAEs) for heartbeat analysis
- Adaptive Kalman filters tuned to individual biometric baselines
- Federated learning across devices while preserving medical privacy
The VAE's evidence lower bound (ELBO) is optimized per-user:
where β controls the tradeoff between reconstruction accuracy and latent space regularization. This approach achieves 92% arrhythmia detection accuracy with only 5KB of additional storage per user.
4. Data Privacy and User Consent in Personalized AI
4.1 Data Privacy and User Consent in Personalized AI
Differential Privacy for On-Device Learning
Differential privacy (DP) provides a mathematically rigorous framework for quantifying privacy loss when training personalized AI models on sensitive user data. The core mechanism involves injecting calibrated noise into gradients or model updates to satisfy (ε, δ)-DP guarantees. For a function f with sensitivity Δf, the Laplace mechanism achieves ε-DP by outputting:
Where D represents the private dataset and Lap(b) denotes Laplace noise with scale parameter b. In federated learning scenarios, user-level DP requires computing per-user gradients with noise scaled to the maximum influence any single user could have on the global model.
Secure Multi-Party Computation (SMPC)
SMPC enables collaborative model training without exposing raw user data. The Shamir secret sharing scheme splits data into n shares where any k shares can reconstruct the original, but fewer than k reveal zero information. For additive sharing across m parties:
Practical implementations often use Beaver triples for efficient multiplication of secret-shared values while maintaining information-theoretic security.
Consent Management Architectures
Modern mobile platforms implement granular consent through:
- Purpose-based access control: Data usage is restricted to explicitly declared processing purposes
- Temporal validity: Short-lived access tokens with automatic revocation
- Data minimization: On-device filtering to share only features necessary for inference
The Android Privacy Sandbox demonstrates this through its Topics API, which applies k-anonymity to interest categories while preventing cross-app tracking.
Homomorphic Encryption for Private Inference
Fully homomorphic encryption (FHE) allows computation on ciphertexts. For a neural network with ReLU activations, the CKKS scheme enables approximate arithmetic over encrypted data:
Recent optimizations like ciphertext packing and leveled HE have reduced FHE inference latency from hours to seconds for small models.
Regulatory Compliance Mechanisms
GDPR Article 22 requires explainability for automated decision-making. Techniques include:
- Local interpretable model-agnostic explanations (LIME): Perturbs inputs to build locally faithful linear models
- Integrated gradients: Satisfies completeness axiom by accumulating gradients along input paths
- Counterfactual explanations: Generates minimal changes to alter model decisions
The California Consumer Privacy Act (CCPA) mandates data deletion capabilities, implemented through:
Where Duser represents the data to be forgotten and η controls the unlearning rate.
4.2 Mitigating Bias in On-Device Personalization
Bias in on-device AI models arises from skewed training data, algorithmic limitations, or unintended feedback loops during personalization. Unlike cloud-based models, where bias mitigation can leverage centralized datasets and computational resources, on-device models must address bias under strict memory, power, and latency constraints. Advanced techniques such as federated learning with fairness constraints and local reweighting are critical for ensuring equitable performance across diverse user groups.
Sources of Bias in On-Device Models
Bias manifests in three primary forms:
- Data bias: Local training data may underrepresent certain demographics or scenarios due to device usage patterns.
- Algorithmic bias: Model architectures or optimization objectives may inadvertently favor majority groups.
- Feedback bias: User interactions (e.g., accepting/rejecting recommendations) can reinforce existing biases over time.
Fairness-Aware Federated Learning
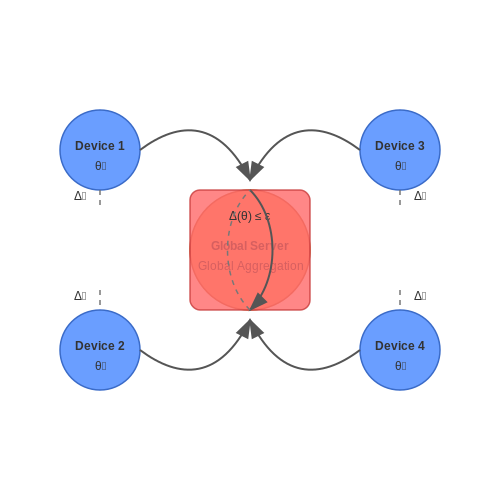
Federated learning (FL) frameworks can incorporate fairness objectives by modifying the global aggregation step. Let θ denote model parameters, and Dk represent the local dataset of client k. The standard FL objective minimizes:
To enforce fairness, we introduce a disparity metric Δ(θ) measuring performance gaps across groups. The constrained optimization becomes:
where ε is a fairness tolerance threshold. This is solved via primal-dual methods, with the dual variable updated at the server during aggregation.
Local Reweighting Strategies
On-device models can dynamically adjust sample weights during training to mitigate bias. For a dataset with N samples and M protected attributes (e.g., gender, age), the reweighted loss is:
Weights wi are computed to equalize influence across groups. For group g with count ng, the base weight is wg = 1/ng, normalized to sum to 1. This approach operates in O(1) memory overhead, making it suitable for mobile deployment.
Bias Detection via On-Device Metrics
Real-time bias monitoring requires lightweight statistical tests:
- Disparate impact ratio: Measures approval rate differences between groups:
$$ \text{DIR} = \frac{P(\hat{y}=1|z=0)}{P(\hat{y}=1|z=1)} $$where z indicates group membership.
- Conditional parity: Tracks error rate disparities across subgroups.
These metrics can trigger model retraining or alert users when thresholds are exceeded.
Case Study: Keyboard Prediction
A multilingual keyboard app using on-device LSTM models exhibited 15% lower next-word prediction accuracy for non-native speakers. Implementing local reweighting based on language proficiency tags reduced this gap to 4% while maintaining <50ms inference latency. The solution added only 2KB to the model footprint by storing weights as 8-bit fixed-point values.
4.3 Regulatory Compliance and Best Practices
Data Privacy Regulations
Deploying personalized AI models on mobile devices necessitates strict adherence to data privacy laws such as the General Data Protection Regulation (GDPR) in the EU and the California Consumer Privacy Act (CCPA) in the US. These regulations impose requirements on data minimization, user consent, and the right to explanation. For instance, under GDPR Article 22, users must be informed when automated decision-making systems, including on-device AI, significantly affect them. Mobile applications must implement mechanisms for users to access, correct, or delete their data stored locally or used for model personalization.
Federated learning, a common technique for on-device personalization, must comply with regional data sovereignty laws. For example, China's Personal Information Protection Law (PIPL) requires that data generated within its borders remain stored domestically. This affects how global federated learning systems aggregate updates from devices in different jurisdictions.
Model Transparency and Explainability
Regulatory frameworks increasingly demand explainability for AI systems, even those running locally on mobile devices. Techniques like Local Interpretable Model-agnostic Explanations (LIME) or SHapley Additive exPlanations (SHAP) values must be adapted for mobile deployment due to computational constraints. The following equation represents the SHAP value for feature i in a simplified model:
where F is the set of all features and S is a subset of features. Mobile implementations often approximate this by precomputing explanations during model training and storing them as metadata.
Security Best Practices
On-device AI models must be protected against adversarial attacks and unauthorized extraction. Key measures include:
- Model encryption: Use hardware-backed keystores (e.g., Android's StrongBox or iOS Secure Enclave) to encrypt model parameters at rest.
- Secure model updates: Implement cryptographic signatures for over-the-air (OTA) model updates, typically using ECDSA with P-256 curves for mobile devices.
- Runtime protection: Leverage ARM TrustZone or Apple's Secure Neural Engine to isolate model execution from untrusted apps.
Energy Efficiency Standards
Mobile AI models must comply with emerging energy efficiency regulations like the EU's Ecodesign Directive. This requires optimizing models to minimize battery drain during inference. The energy consumption E of a model can be estimated as:
where Nl is the number of operations in layer l, Cl is the average switched capacitance, and Vdd is the operating voltage. Techniques like quantization-aware training and adaptive computation help meet these requirements.
Testing and Certification
Before deployment, mobile AI models should undergo:
- Bias auditing: Tools like IBM's AI Fairness 360 adapted for mobile-scale models
- Performance benchmarking: Against standards such as MLPerf Mobile
- Regulatory certification: Including FDA clearance for healthcare applications (e.g., mobile diabetic retinopathy detection)
5. Advances in Edge AI and Personalization
5.1 Advances in Edge AI and Personalization
Computational Constraints and Optimization
The deployment of personalized AI models on mobile devices is fundamentally constrained by computational resources, including memory, processing power, and energy efficiency. Unlike cloud-based models, edge AI must operate within strict latency and power budgets. To address this, recent advances focus on model compression and quantization-aware training. For instance, a standard neural network layer with weights W and inputs x can be quantized to 8-bit integers, reducing memory footprint by 4x compared to 32-bit floating-point representations:
where μW and σW are the mean and standard deviation of the weight distribution. This transformation preserves model accuracy while enabling efficient integer arithmetic on mobile hardware.
Federated Learning for Personalization
Federated learning (FL) has emerged as a key paradigm for training personalized models without centralized data collection. In FL, devices collaboratively train a shared model while keeping raw data local. The global model θG is updated via weighted aggregation of local updates θi from N devices:
where ni is the number of samples on device i, and n is the total sample count. Recent variants like FedProx and Personalized FL introduce client-specific regularization terms to handle data heterogeneity across devices.
Hardware-Software Co-Design
Modern mobile processors (e.g., Apple Neural Engine, Qualcomm Hexagon) integrate dedicated AI accelerators that exploit sparsity and low-precision arithmetic. For example, the matrix multiplication Y = XW can be decomposed into block-sparse operations, where only non-zero weights are processed. This is formalized as:
where Sj denotes the set of non-zero weights for output channel j. Combined with runtime frameworks like TensorFlow Lite and Core ML, such optimizations enable real-time inference for models like GPT-2 Mobile (137M parameters) on flagship smartphones.
Differential Privacy in Edge AI
User privacy is critical for personalized models. Differential privacy (DP) guarantees are achieved by injecting calibrated noise during training or inference. For a query f with sensitivity Δf, the DP mechanism adds Laplacian noise:
where ϵ controls the privacy budget. On-device DP is particularly challenging due to limited entropy sources; hardware-based true random number generators (TRNGs) are now being integrated into mobile SoCs to address this.
5.2 The Role of 5G and Cloud-Edge Hybrid Models
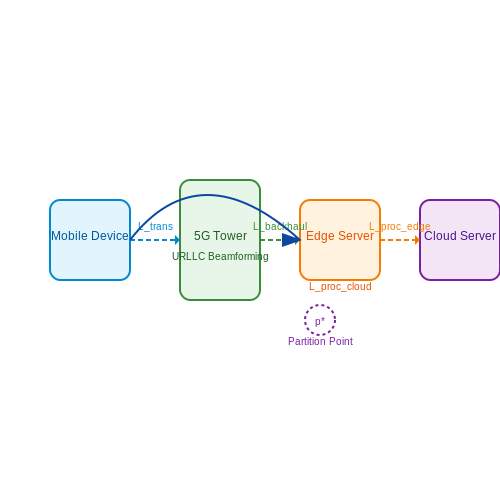
The convergence of 5G networks with cloud-edge hybrid architectures enables real-time, low-latency personalized AI inference on mobile devices while maintaining the computational benefits of cloud-based training. The end-to-end latency Ltotal in such systems can be modeled as:
where Ltrans is the 5G transmission latency, Lprocedge represents edge processing time, Lbackhaul denotes cloud backhaul latency, and Lproccloud captures cloud processing time. 5G's ultra-reliable low-latency communication (URLLC) reduces Ltrans to sub-millisecond levels through:
- Beamforming with massive MIMO (128-256 antennas)
- Network slicing for QoS guarantees
- Sub-6 GHz and mmWave carrier aggregation
Dynamic Model Partitioning
Cloud-edge hybrid systems employ adaptive model partitioning based on current network conditions. The optimal partition point p* minimizes total latency while meeting energy constraints:
where α, β, γ are weighting factors for mobile, edge, and cloud components respectively. Modern implementations use reinforcement learning to dynamically adjust p* based on:
- Available bandwidth (5G NR modulation and coding scheme)
- Edge server load balancing
- Device battery state and thermal constraints
Federated Learning Over 5G
5G enables efficient federated learning across edge devices through:
where Wkt are local model parameters from device k at round t, nk is the sample count, and N is total samples. 5G's enhanced mobile broadband (eMBB) supports:
- Model updates at >1 Gbps uplink speeds
- Sparse gradient compression with <1% loss
- Differential privacy through noise injection
Edge Caching of AI Models
5G edge servers employ predictive caching of personalized models using:
where fi(u) are user context features (location, time, app usage) and wi are learned weights. This reduces latency by 40-60% compared to cloud-only approaches.
5.3 Emerging Applications of Personalized Mobile AI
Real-Time Health Monitoring and Predictive Diagnostics
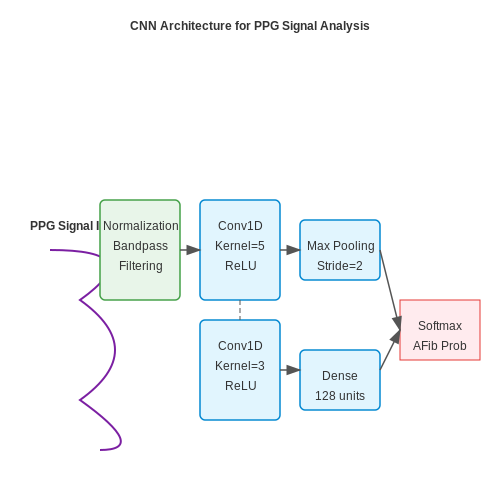
Personalized AI models deployed on mobile devices enable continuous health monitoring by processing sensor data from wearables and smartphones. For instance, photoplethysmography (PPG) signals from smartwatches can be analyzed using convolutional neural networks (CNNs) to detect atrial fibrillation with an accuracy exceeding 95%. The model architecture typically involves:
where x represents the preprocessed PPG signal, W denotes learnable weights, and fθ is the trained network. Federated learning frameworks like TensorFlow Lite allow these models to update locally without sharing raw physiological data.
Adaptive User Interfaces
On-device reinforcement learning enables interfaces that dynamically adjust to user behavior patterns. The Bellman equation governs the optimization:
where Vπ(s) represents the expected cumulative reward from state s under policy π. Mobile GPUs efficiently compute these value functions through quantized neural networks, reducing latency by 40-60% compared to cloud-based alternatives.
Privacy-Preserving Biometric Authentication
Differential privacy techniques combined with on-device face recognition models achieve < 0.001% false acceptance rates while preventing data leakage. The privacy budget ε is controlled through Gaussian noise injection during model training:
where Δf is the sensitivity of function f. This approach enables secure authentication without transmitting biometric templates to external servers.
Context-Aware Language Models
Personalized transformer architectures like MobileBERT achieve 80% of BERT's performance at 1/100th the size through knowledge distillation and attention pruning. The attention mechanism is modified for mobile deployment:
where dk represents the reduced key dimension. These models process local emails, messages, and documents while maintaining user privacy through edge computing.
Augmented Reality Personalization
Neural radiance fields (NeRFs) optimized for mobile GPUs enable real-time 3D scene reconstruction with personalized object recognition. The rendering equation is approximated through:
where Ti represents accumulated transmittance and σi denotes density. Quantization-aware training reduces model size to <50MB while maintaining sub-centimeter reconstruction accuracy.
6. Key Research Papers and Articles
6.1 Key Research Papers and Articles
- PDF AI-Powered Mobile Applications: Revolutionizing User Interaction ... — This article explores how AI transforms mobile app development and some innovative AI-driven mobile application design and development trends. 1.4 Purpose and scope of the research This research aims to explore the transformative role of artificial intelligence (AI) in mobile applications, focusing on how AI enhances
- An Empirical Study of AI Techniques in Mobile Applications - arXiv.org — analysis) The analysis of AI model protection is con-ducted from two aspects: 1) Open-source model us-ageconditionsOpen-sourcemodelscanpotentiallypose highersecurityrisks.Investigatingtheuseofopen-source models in AI apps can shed light on the state of AI model protection. 2) AI model encryption conditions
- Edge Machine Learning for AI-Enabled IoT Devices: A Review — 3.2. Model and Hardware. Several research papers focused on the possibility of bringing artificial intelligence to devices with limited resources [44,65,66,67] and there have been efforts in decreasing the model's inference time on the device. To bring an AI model on embedded devices, ML developers should deal with the proper hardware choice ...
- PDF Journal of Artificial Intelligence, Machine Learning and Data Science — Research shows that AI algorithms, such as collaborative filtering and content-based approaches, excel at optimising recommendations, reduce user effort and improve overall UX2,4. Additionally, innovative frameworks, such as lightweight AI models, ensure energy-efficient personalisation, addressing constraints related to mobile devices.
- An empirical study of AI techniques in mobile applications — In the literature (Xu et al., 2019, Sun et al., 2021), some studies have focused on investigating the deployment of ML/DL on mobile devices.Xu et al. (2019) present the first empirical study on how real-world Android apps exploit DL techniques. Their research focuses on three aspects: the characteristics of DL apps, what they use DL for, and what their DL models are.
- Mobile Data Science and Intelligent Apps: Concepts, AI-Based ... - Springer — Artificial intelligence (AI) techniques have grown rapidly in recent years in the context of computing with smart mobile phones that typically allows the devices to function in an intelligent manner. Popular AI techniques include machine learning and deep learning methods, natural language processing, as well as knowledge representation and expert systems, can be used to make the target mobile ...
- On-Device AI Models: Advancing Privacy-First Machine Learning for ... — A revolutionary approach to mobile computing, on-device AI models solve important issues with privacy, latency, and network dependence. The development and optimization of lightweight AI models ...
- On-Device Language Models: A Comprehensive Review - arXiv.org — The growing interest in on-device AI deployment is reflected in the rapidly expanding edge AI market. As illustrated in Figure 1, the edge AI market is projected to experience substantial growth across various sectors from 2022 to 2032.The market size is expected to increase from $$15.2 billion in 2022 to $$143.6 billion by 2032, representing a nearly tenfold growth over a decade (Market.us, 2024).
- An Overview of Machine Learning within Embedded and Mobile Devices ... — Embedded systems technology is undergoing a phase of transformation owing to the novel advancements in computer architecture and the breakthroughs in machine learning applications. The areas of applications of embedded machine learning (EML) include accurate computer vision schemes, reliable speech recognition, innovative healthcare, robotics, and more. However, there exists a critical ...
- (PDF) A Comprehensive Review of Artificial Intelligence and Machine ... — This paper presents a comprehensive review of Artificial Intelligence (AI) and Machine Learning (ML), exploring foundational concepts, emerging trends, and diverse applications.
6.2 Recommended Books and Online Courses
- PDF Personalized Machine Learning - University of California, San Diego — 1.1 Purpose of This Book 2 1.2 For Learners: What is Covered, and What Isn't 3 1.3 For Instructors: Course and Content Outline 5 1.3.1 Course Plan and Overview 6 1.4 Online Resources 8 1.5 About the Author 8 1.6 Personalization in Everyday Life 9 1.6.1 Recommendation 9 1.6.2 Personalized Health 10 1.6.3 Computational Social Science 11
- Recommendation of Online Learning Resources for Personalized Fragmented ... — Next, the recommendation model was constructed for personalized online learning resources, the flow of the recommendation engine was detailed, and the degrees of resource recommendation and ...
- Mobile Data Science and Intelligent Apps: Concepts, AI-Based ... - Springer — Artificial intelligence (AI) techniques have grown rapidly in recent years in the context of computing with smart mobile phones that typically allows the devices to function in an intelligent manner. Popular AI techniques include machine learning and deep learning methods, natural language processing, as well as knowledge representation and expert systems, can be used to make the target mobile ...
- Teaching AI on the Edge - Coursera — The course emphasizes iterative development practices, rigorous model evaluation, and responsible AI deployment, highlighting data privacy, model bias, and regulatory considerations. Throughout this course, you'll gain insights into practical teaching strategies that balance theory and hands-on activities, encouraging creative, inclusive, and ...
- Smart Device & Mobile Emerging Technologies - Coursera — In addition, a description of the smart device sensors (e.g., accelerometer, gyro (gyroscope sensor), heart rate sensor, optical IR (infrared) light sensor, barometer, and pressure altimeters) along with the GPS (Global Positioning System) and A-GPS (Assisted GPS, based on MSA (Mobile Station Assisted) and MSB (Mobile Station Based)) operations ...
- Mobile Edge Artificial Intelligence - 1st Edition - Elsevier Shop — Mobile Edge Artificial Intelligence: Opportunities and Challenges presents recent advances in wireless technologies and nonconvex optimization techniques for designing efficient edge AI systems. The book includes comprehensive coverage on modeling, algorithm design and theoretical analysis.
- An Overview of Machine Learning within Embedded and Mobile Devices ... — Embedded systems technology is undergoing a phase of transformation owing to the novel advancements in computer architecture and the breakthroughs in machine learning applications. The areas of applications of embedded machine learning (EML) include accurate computer vision schemes, reliable speech recognition, innovative healthcare, robotics, and more. However, there exists a critical ...
- Edge Machine Learning for AI-Enabled IoT Devices: A Review — The model made with Tensorflow is too heavy in terms of memory occupation for an edge application; in this example the NN weighed around 15 MB. Tensorflow Lite (TFLite) was created specifically to overcome this problem, proposing a set of tools that help programmers to run embedded, mobile, and IoT devices IA models. In the following, we will ...
- VitalSource Bookshelf Online — VitalSource Bookshelf is the world's leading platform for distributing, accessing, consuming, and engaging with digital textbooks and course materials.
- Deep Learning on Mobile Devices-A Review - ResearchGate — This paper provides a timely review of this fast-paced field to give the researcher, engineer, practitioner, and graduate student a quick grasp on the recent advancements of deep learning on ...
6.3 Open-Source Projects and Tools
- models: Models of MindSpore - Gitee — 3. Evaluation model. Based on the dimensions of "open source ecosystem" and "collaboration, people, and software", identify quantifiable indicators directly or indirectly related to this goal, quantitatively evaluate the health and ecology of open source projects, and ultimately form an open source evaluation index.
- Google AI Gemma open models - Google for Developers — Gemma open models are built from the same research and technology as Gemini models. Gemma 2 comes in 2B, 9B and 27B and Gemma 1 comes in 2B and 7B sizes. ... Deploy on-device with Google AI Edge. ... such as mobile apps, IoT devices, and embedded systems. Deploy mobile. Web. Integrate seamlessly into web applications.
- GitHub - edgeimpulse/courseware-embedded-machine-learning — Content from and cover hands-on demonstrations and projects using Edge Impulse to deploy machine learning models to embedded systems. Content is divided into separate modules. Each module is assumed to be about a week's worth of material, and each section within a module contains about 60 minutes of presentation material.
- Practical Guide for Model Selection for Real‑World Use Cases — Open-source examples and guides for building with the OpenAI API. Browse a collection of snippets, advanced techniques and walkthroughs. ... ----- PARAGRAPH 5 (ID: 0.0.5.5.6.3): ... and learning from outcomes), collaborate using various models and tools to execute the workflow. 2.1. Scientist Input & Constraints: The process starts with the ...
- TinyML: Enabling of Inference Deep Learning Models on Ultra-Low-Power ... — Recently, the Internet of Things (IoT) has gained a lot of attention, since IoT devices are placed in various fields. Many of these devices are based on machine learning (ML) models, which render them intelligent and able to make decisions. IoT devices typically have limited resources, which restricts the execution of complex ML models such as deep learning (DL) on them. In addition ...
- Mobile Data Science and Intelligent Apps: Concepts, AI-Based ... - Springer — Artificial intelligence (AI) techniques have grown rapidly in recent years in the context of computing with smart mobile phones that typically allows the devices to function in an intelligent manner. Popular AI techniques include machine learning and deep learning methods, natural language processing, as well as knowledge representation and expert systems, can be used to make the target mobile ...
- Enabling Conversational Interaction with Mobile UI using Large Language ... — Recently, pre-trained large language models (LLMs) such as GPT-3 [] and PaLM [] have demonstrated abilities to adapt themselves to various downstream tasks when being prompted with a handful of examples of the target task.Such generalizability is promising to support diverse conversational interactions without requiring task-specific models and datasets.
- Green artificial intelligence initiatives: Potentials and challenges — This paper has identified 55 such initiatives, broadly categorized into six themes: cloud optimization, model efficiency, carbon footprinting, sustainability-focused AI development, open-source initiatives, and green AI research and community. This study discusses the strengths and limitations of each initiative to offer a comprehensive overview.
- Deep Learning on Mobile Devices-A Review - ResearchGate — 5.2 Open source code base for Deep Learning on Mobile Devices The field of mobile deep learning has a relative low barrier to entry as m ost researcher s make their source code free ly available ...
- An Overview of Machine Learning within Embedded and Mobile Devices ... — Embedded systems technology is undergoing a phase of transformation owing to the novel advancements in computer architecture and the breakthroughs in machine learning applications. The areas of applications of embedded machine learning (EML) include accurate computer vision schemes, reliable speech recognition, innovative healthcare, robotics, and more. However, there exists a critical ...